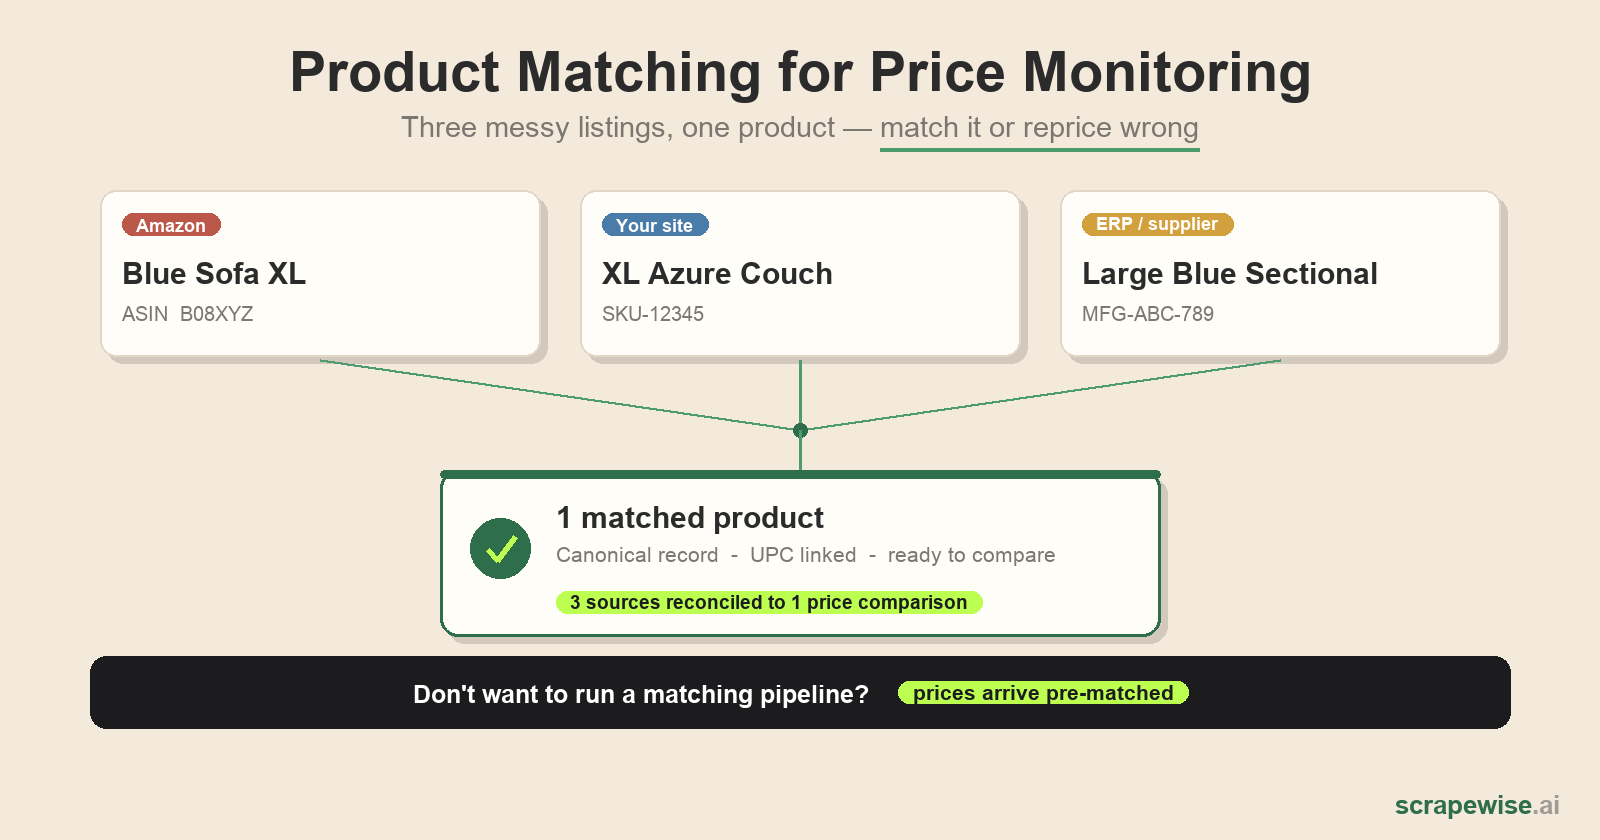
Most competitive price feeds fail quietly. Not because the scraper missed a page — because the row it returned is matched to the wrong product. Your 55" OLED gets compared against a competitor's 50" LED, the repricing engine drops your price, and margin leaks on a match nobody checked.
Product matching — linking your SKU to the identical competitor listing despite different names, SKUs, and attributes — is the layer that decides whether a price feed is usable. Scraping is the easy half. Matching is where competitor data is right or wrong.
Which Matching Approach Fits Your Catalog?
| Your situation | Best fit |
|---|---|
| Products carry clean UPC/EAN/GTIN | Exact identifier match |
| Titles vary but are broadly similar | Fuzzy text match |
| Rich structured specs, few identifiers | Attribute match |
| Messy, multi-source, high-value catalog | AI ensemble (text + vision + attributes) |
The Four Matching Methods, Honestly
| Method | Best when | Where it breaks |
|---|---|---|
| Exact ID (UPC/EAN/GTIN) | Identifiers present and shared | Marketplaces strip or fake identifiers |
| Fuzzy text | Titles are close | "XL Azure Couch" vs "Large Blue Sectional" |
| Attribute | Complete structured specs | Sparse or inconsistent attribute data |
| AI ensemble | Messy real-world data | Cost/complexity; still needs review on edge cases |
Why Price Monitoring Fails Without It
A price is only meaningful next to the right comparison. When matching is weak, three failures compound:
- False positives — your product matched to a cheaper, different item. The engine underprices you and margin bleeds.
- False negatives — a real competitor listing goes unmatched, so you never react to their price move.
- Silent drift — a competitor relists under a new title or bundle, the old match breaks, and the feed keeps reporting a stale or wrong number.
None of these show up as an error. The feed looks healthy; the decisions built on it are wrong.
How to Evaluate a Matching Layer
Don't ask for "accuracy" as a single number — ask for two:
- Precision: of the matches returned, how many are correct? Low precision = you reprice against wrong products.
- Recall: of the competitor products that exist, how many did it match? Low recall = blind spots you never price against.
A vendor quoting one without the other is hiding the trade-off. Also test on sparse and messy data, not a clean sample — real catalogs are messy, and that's exactly where naive fuzzy matching collapses.
Matching as Part of the Feed, Not a Separate Project
You can build matching in-house — an ensemble of NLP, computer vision, and attribute scoring with a human-review queue — as covered in our product data matching guide. Or you can have it handled inside the data feed itself.
A managed price monitoring infrastructure like ScrapeWise returns competitor prices already matched to your SKUs — you don't run a separate matching pipeline. In internal testing (Apr 2026) it reached 97% SKU coverage and 96% anti-bot success on Amazon EU, with scheduled or on-demand runs, so the price you see is tied to the right product, not a lookalike.
How to Choose
- Do your products carry real identifiers? If yes, start with exact ID and use fuzzy/attribute as fallback.
- How messy is your competitor data? Marketplace-heavy → you need ensemble matching, not string similarity.
- Do you want to own a matching pipeline? If not, choose a feed that returns pre-matched competitor prices.
The Bottom Line
Scraping gets you rows; matching decides whether those rows mean anything. Judge any competitor price feed on precision and recall against messy data — and if you'd rather not run a matching pipeline at all, choose a feed that delivers competitor prices already matched to your catalog.
Paste a competitor URL and start tracking prices
Any e-commerce site, any SKU count. Clean structured feeds on your schedule, no code required.
Not ready to sign up? See 40 rows of real Google Shopping price data →
97% accuracy on Amazon benchmarks · no credit card · book a 15-min call →