If you've outgrown raw proxies but don't want to run a headless-browser fleet, a scraping API is the middle path. You send a URL, the service handles proxies, JavaScript rendering, and anti-bot, and returns the HTML. The three names that dominate this tier are ScrapingBee, ScraperAPI, and ZenRows — similar on the surface, different in where they put their engineering.
The honest caveat first: a scraping API returns HTML, not data. You still write and maintain the parsing on top, and you still babysit success rates when a target hardens. It removes the proxy layer, not the operation.
Which One Fits Your Situation?
| Your situation | Better fit |
|---|---|
| Simple API, good docs, JS rendering that "just works" | ScrapingBee |
| Highest volume at the lowest per-request price | ScraperAPI |
| Toughest anti-bot targets (Cloudflare, DataDome) | ZenRows |
| Don't want to parse or maintain scrapers at all | Managed data feed |
Quick Comparison
| ScrapingBee | ScraperAPI | ZenRows | |
|---|---|---|---|
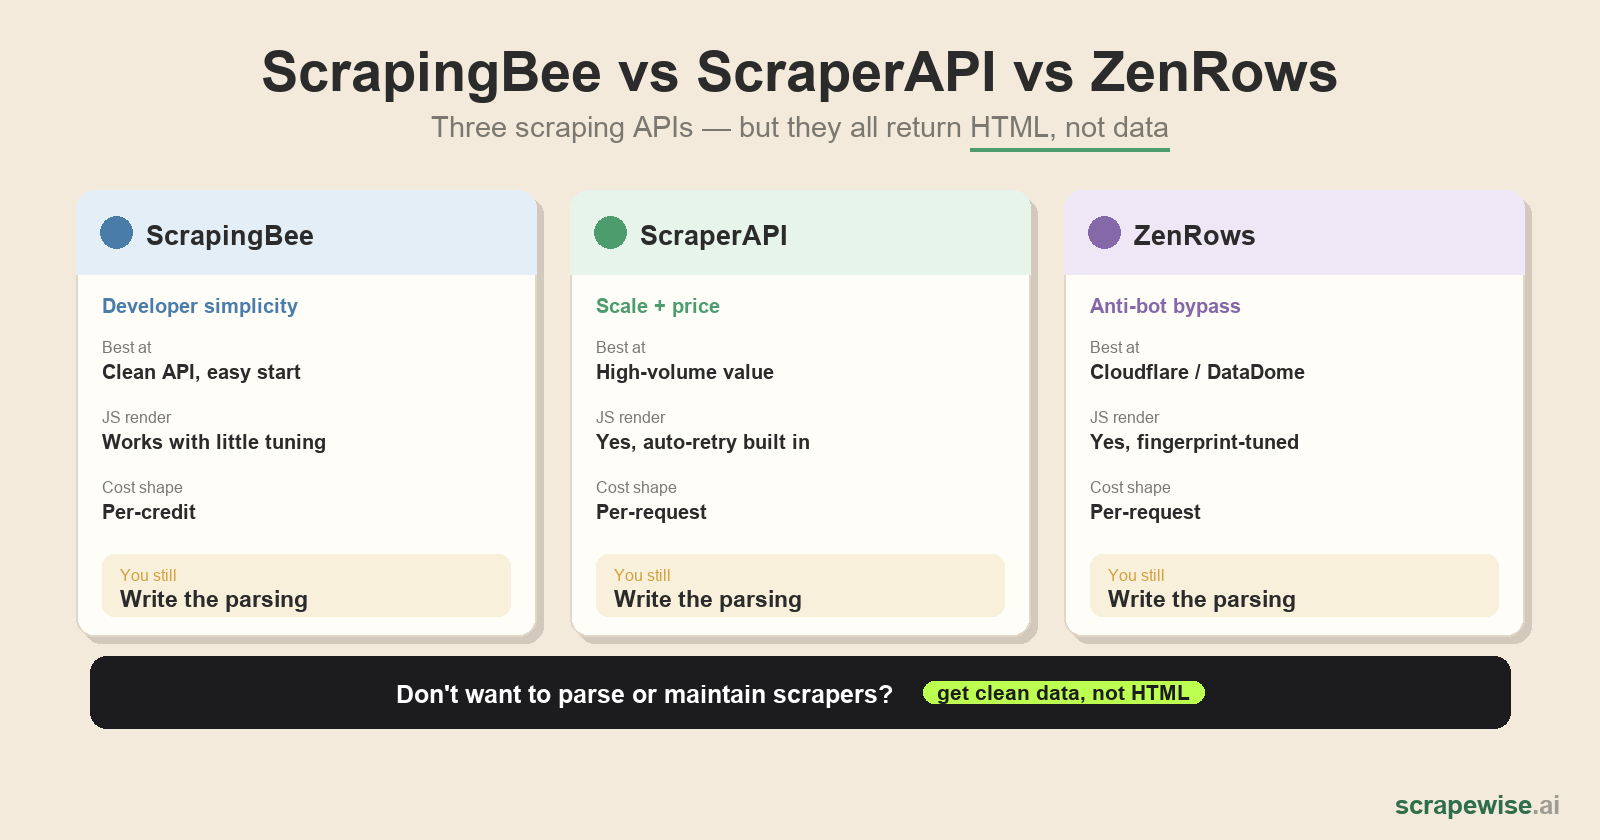
| Focus | Developer simplicity | Scale + price | Anti-bot bypass |
| JS rendering | Yes | Yes | Yes |
| Best at | Clean API, easy start | High-volume value | Hard targets |
| You still do | Parsing | Parsing | Parsing |
| Pricing | Per-credit | Per-request | Per-request |
ScrapingBee: Developer Simplicity
ScrapingBee optimizes for the developer experience — clean API, solid documentation, and JavaScript rendering that works without much tuning. For teams that want to point an API at a URL and get rendered HTML back with minimal setup, it's the least-friction option.
The trade-off is that on the hardest anti-bot targets it can lag the more specialized services, and credit-based pricing gets expensive as rendering and premium proxies stack up.
ScraperAPI: Scale and Price
ScraperAPI leans into volume. Its pricing rewards high request counts, making it the value pick when you're scraping a lot and each request is relatively cheap to fulfill. Auto-retry and proxy rotation are baked in.
The trade-off is that the cheapest tiers lean on datacenter proxies, so on well-defended sites you pay up for residential and rendering — and success rates on the hardest targets trail a bypass-focused tool.
ZenRows: Anti-Bot Bypass
ZenRows positions squarely on the hardest problem — getting past modern anti-bot like Cloudflare and DataDome. If your bottleneck is blocking rather than rendering or price, its fingerprinting and bypass tuning is the differentiator.
The trade-off is that this specialization comes at a price point above the value tier, and like the others it still hands you HTML to parse yourself.
The Common Ceiling: They Return HTML, Not Data
All three stop at the same line. They get you rendered, unblocked HTML — then you write CSS/XPath selectors, maintain them when the site changes, structure the output, and monitor success rates. The scraping API removes proxies and rendering; it doesn't remove the scraper.
A managed data infrastructure closes that last gap: you name the URL and receive clean structured records — proxies, fingerprinting, rendering, and parsing handled. In internal testing (Apr 2026) ScrapeWise returned 97% SKU coverage and 96% anti-bot success on Amazon EU, with scheduled or on-demand runs, on pay-per-use pricing. See scraping without getting blocked for the architecture behind it.
How to Choose
- What's your bottleneck? Simplicity → ScrapingBee. Price at volume → ScraperAPI. Blocking → ZenRows.
- How hard are your targets? Cloudflare/DataDome-heavy → ZenRows earns its premium.
- Do you want HTML or data? If you'd rather skip parsing and maintenance entirely, a managed feed removes the whole layer.
The Bottom Line
ScrapingBee wins on developer experience, ScraperAPI on volume pricing, ZenRows on beating hard anti-bot. But all three return HTML you still have to parse and maintain — and if you'd rather receive clean data, a managed feed removes the operation instead of relocating it.
Paste any URL — ScrapeWise handles the anti-bot
Managed infrastructure that adapts when sites change. No proxies, no code, no per-request fees.
Not ready to sign up? See 12 real Amazon rows, 972 columns →
97% accuracy on Amazon benchmarks · no credit card · book a 15-min call →